- AI agents
- agentic AI
- security architecture
- human approval
- governance
AI Agents Need an Authority Ladder
Give an agent more authority only when the use case has earned stronger identity, evaluation, approval, audit, and recovery controls.

Jason Cochran
AI agents are often described by capability: which models they use, how many tools they can call, and whether they can plan across multiple steps.
Enterprise architecture needs a second description: what authority does each agent have?
An agent that summarizes approved documents and one that can change production configuration are not variations of the same risk. The system should make that difference structural.
Separate four levels of authority
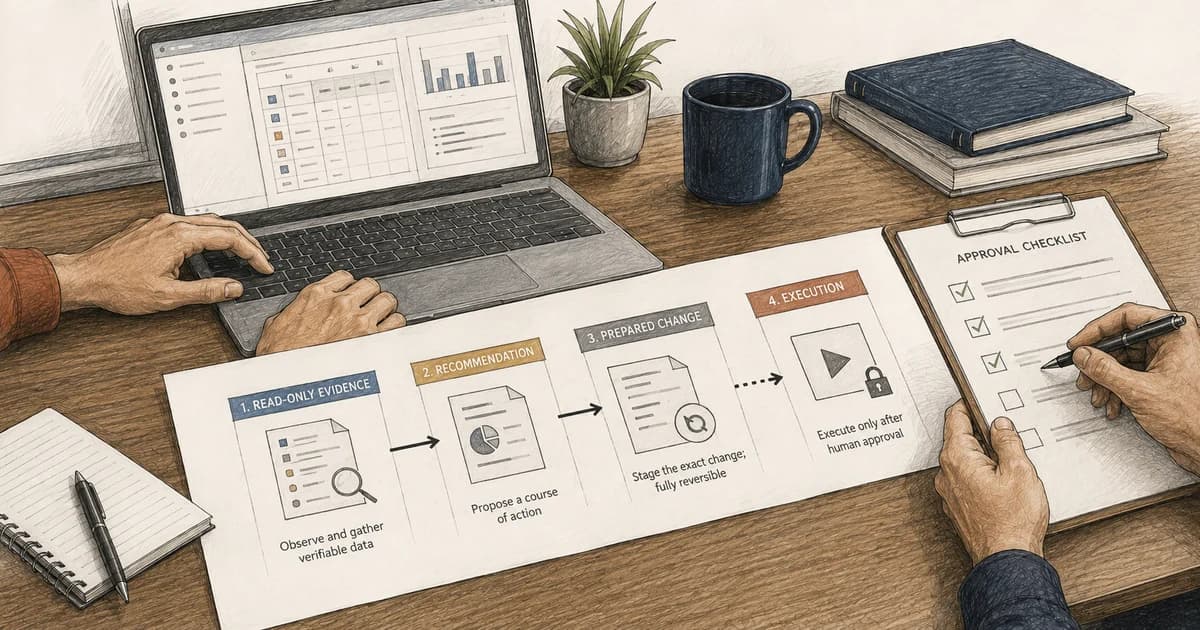
Use a four-rung ladder: read, recommend, prepare, execute.
Authority ladder
Decision frameworkIncrease agent authority one rung at a time
Separate what an AI system may recommend from what it may change, then require stronger evidence at every rung.
- 01
Read
Retrieve approved information with source, tenant, and sensitivity boundaries.
- 02
Recommend
Draft an answer or proposed action while a person owns the decision.
- 03
Prepare
Create a reversible change for explicit human review and approval.
- 04
Execute
Act only inside narrow policy, budget, identity, audit, and recovery controls.
Controls grow by rung
- Stronger identity and authorization
- Broader evaluation and monitoring
- Tighter budgets, approval, and recovery
Stop escalation when
- The action is irreversible
- The reviewer lacks context
- Failure cannot be bounded or reconciled
Read retrieves approved information without durable side effects. Recommend interprets evidence and proposes a decision. Prepare creates a specific, reversible change for review. Execute performs an approved business or technical action.
Each rung requires stronger controls. An agent having a tool is not evidence that it should receive execute permission.
Keep read access permission-aware
Read-only still carries risk. An agent can combine information, reveal restricted document titles, or expose data across tenants. Treat retrieval as an authorization decision, not a convenience layer.
Apply the user’s actual permissions during retrieval. Preserve source, sensitivity, and tenant metadata. Test indirect prompt injection in documents and tool responses. Limit what leaves the approved environment and what is retained in traces.
Make recommendations inspectable
A recommendation should show the evidence used, assumptions, uncertainty, and the policy or rule that shaped it. The user must be able to distinguish source facts from model inference.
For oil and gas operations, AI can help summarize an exception or locate procedures, but the qualified person should own the operational decision. Advisory software should not disguise itself as control logic.
Freeze prepared actions for review
At the prepare level, the agent creates an artifact: a pull request, infrastructure plan, draft work order, proposed configuration, or other change set.
The reviewer needs the target, exact change, likely effect, relevant evidence, and recovery approach. Hash or version the proposal and revalidate policy before execution. Otherwise the approved object can differ from what runs.
Constrain execution
Execution should use a narrow workload identity, allowlisted operation, validated schema, idempotency key, budget, timeout, and audit record. Require step-up approval or separation of duties for sensitive actions.
Put hard limits outside the model: number of records, financial amount, environment, site, resource type, and maximum iterations. The agent cannot be the authority that expands its own limits.
Design failure and recovery
An agent may stop midway through a multi-step task. Decide which steps are durable, which are reversible, and how continuation or compensation works. Do not blindly retry an action whose outcome is unknown.
Expose partial progress to support. Record tool calls, results, identifiers, and final state without copying secrets or excessive sensitive content.
Evaluate at every rung
Read access needs permission and retrieval tests. Recommendations need groundedness and usefulness review. Prepared actions need diff accuracy and policy validation. Execution needs end-to-end safety, idempotency, containment, and recovery tests.
Promote an agent only with evidence, and keep the promotion reversible. A successful pilot alone does not justify more authority.
Architecture review questions
- What rung does this use case require today?
- Which user and workload identities are preserved?
- Can retrieved content change instructions or permissions?
- What evidence accompanies a recommendation?
- Is the prepared action stable between approval and execution?
- Which limits are enforced outside the model?
- Can execution be repeated safely?
- What happens after partial completion?
- Can security and support reconstruct the action?
- What evidence would justify the next rung?
Agent architecture improves when authority is explicit. Start with the lowest rung that can answer the user’s need, measure value and failure modes, strengthen controls, and move upward only when the evidence supports it.